The Shrinking Giant: How PrismML is Redefining the Limits of AI Efficiency
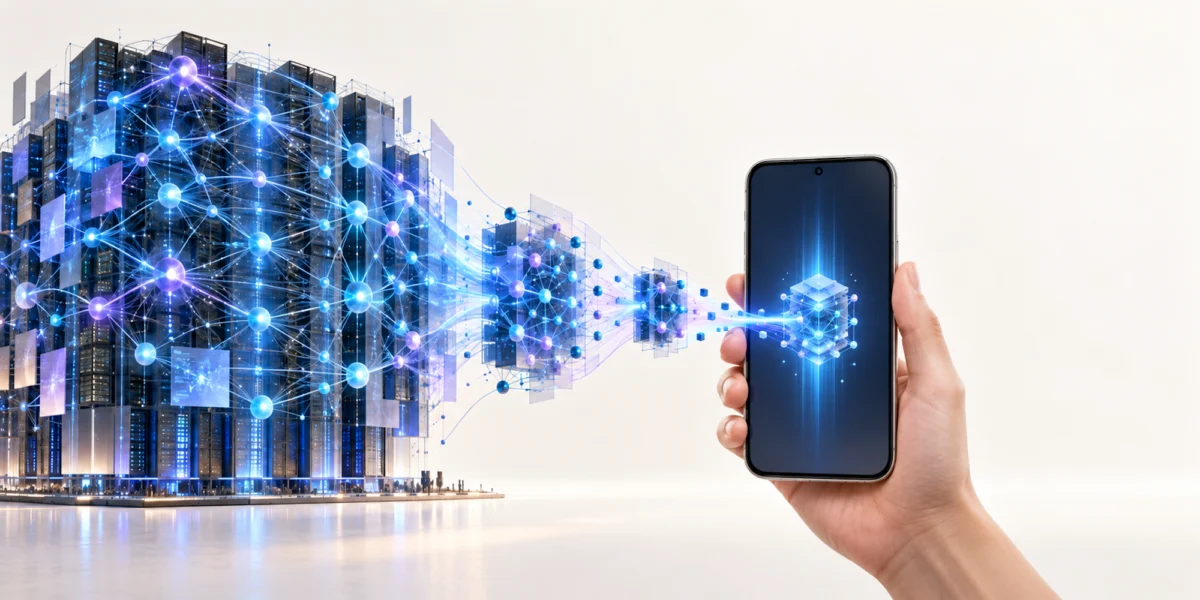
In the rapidly evolving landscape of artificial intelligence, the prevailing narrative has long been "bigger is better." For years, the industry has been locked in an arms race to build increasingly massive large language models (LLMs), with parameter counts stretching into the trillions and hardware requirements necessitating massive, energy-hungry data centers. However, a quiet revolution is brewing in a Caltech-born startup called PrismML.
While the tech world focuses on the sheer scale of the cloud, PrismML is betting on the opposite: that the future of AI lies in radical miniaturization. With the release of their latest model, Bonsai 2 27B, the company is demonstrating that high-level reasoning and sophisticated linguistic capabilities do not require a room full of servers. By shrinking industry-leading models to a fraction of their original size, PrismML is positioning itself to bring "sovereign AI" directly to the palm of a user’s hand.
Breaking the Scale: The Launch of Bonsai 2 27B
On Thursday, PrismML announced the release of Bonsai 2 27B, the newest flagship in its family of compressed models. The technical achievement is staggering: the team has taken Alibaba’s Qwen3.8 27B—a widely respected and powerful open-source model—and compressed it down to just 5.9 GB.
To put this in perspective, the original model typically requires a high-end enterprise GPU with significant VRAM to function effectively. At 5.9 GB, the model can now reside comfortably on a standard consumer PC or even a high-end smartphone. This represents a 9x to 10x reduction in memory footprint compared to the uncompressed original.
The significance of this milestone cannot be overstated. Most "small" models currently on the market are built small from the ground up, which often limits their reasoning capabilities. PrismML’s approach is different; they take an existing "heavyweight" model—one that has already mastered complex reasoning through massive training—and distill its essence into a lightweight frame. The result is a model that retains the "brainpower" of a giant while fitting into the "body" of a mobile app.
A Chronology of Innovation: From Caltech Labs to Global Downloads
The journey of PrismML is rooted in academic excellence and a clear vision for the democratization of AI. Founded by a group of researchers from the California Institute of Technology (Caltech), the startup is led by CEO Babak Hassibi, a Caltech professor and a globally recognized expert in information theory and compression technologies.
The company’s timeline reflects a rapid transition from theoretical research to market-disrupting product releases:
- Early Development: PrismML emerged from the intersection of signal processing and machine learning research at Caltech. The goal was to solve the "inference bottleneck"—the high cost and latency associated with running large models.
- Seed Funding: The company secured a $22.25 million seed round, backed by heavyweight investors including Khosla Ventures (an early backer of OpenAI), Cerberus Capital, and Caltech itself.
- March 2024 – The First Bonsai: PrismML released the first iteration of Bonsai. This model achieved 95% performance parity with its base model and quickly went viral within the developer community, amassing over 11 million downloads.
- Late 2024 – Ecosystem Growth: Following the success of the initial release, the company’s smaller specialized models reached an additional 2.6 million downloads, proving a massive appetite for local, efficient AI.
- Present Day – Bonsai 2: The release of Bonsai 2 27B marks a significant jump in efficiency and accuracy, pushing the performance parity from 95% to 98%.
The startup also benefits from the guidance of Ion Stoica, a co-founder of Databricks and the director of UC Berkeley’s Sky Computing Lab. Stoica’s involvement signals that PrismML is not just a niche compression tool, but a fundamental component of the next generation of computing infrastructure.
The Science of Ternary Weights: How Compression Works
The technical "secret sauce" behind PrismML’s success lies in how they handle the "weights" of a neural network. In a standard LLM, weights—the numerical values that determine how information flows through the model—are typically stored using 16-bit floating-point numbers (FP16).
PrismML utilizes a revolutionary approach called "ternary weights." Instead of using a complex range of 16-bit values, they simplify the weights down to just three possible states: +1, -1, or 0. This "1.58-bit" quantization drastically reduces the amount of data required to store and process each parameter.
Maintaining Performance Parity
The challenge with such aggressive compression has traditionally been "lossiness." Just as a highly compressed JPEG image becomes pixelated, a highly compressed LLM usually loses its ability to reason or maintain grammatical coherence.
However, Hassibi claims PrismML’s tech is unique because it manages to retain virtually all the original performance. Bonsai 2 matches 98% of Qwen’s aggregate benchmark scores. This means that for the vast majority of real-world tasks—coding, summarization, and logical reasoning—a user would be unable to distinguish the 5.9 GB Bonsai model from the original massive version.
The Scaling Law of Compression
Interestingly, Hassibi notes that compression actually becomes more efficient as models get larger. "The next models that we will release… will be in the several-hundred-billion-parameter range," Hassibi told TechCrunch. "As model size grows, there is more room to be able to compress them without losing the intelligence. For larger models, it’s easier to get to 100% parity."
Market Positioning and the Apple Connection
PrismML enters a competitive field where other players, such as Multiverse Computing, are also exploring AI compression through different mathematical lenses (like tensor networks). However, PrismML’s traction in the open-source community gives it a distinct advantage in terms of real-world testing and adoption.
One of the most persistent rumors surrounding the startup is its potential involvement with Apple. As Apple prepares to roll out "Apple Intelligence" across its ecosystem, the tech giant faces a major hurdle: how to run sophisticated AI on iPhones without draining the battery or relying entirely on the cloud.
Industry analysts have noted that PrismML’s ability to fit a 27B parameter model into 5.9 GB aligns perfectly with the hardware constraints of the iPhone’s Neural Engine. While Hassibi declined to comment on talks with Apple, the strategic fit is undeniable. If Apple—or any major smartphone manufacturer—integrates PrismML’s technology, it would instantly turn billions of devices into high-powered AI workstations.
Official Responses: Privacy, Cost, and Autonomy
The leadership at PrismML views their work as a necessary correction to the current "Cloud-First" AI model. In discussions regarding the release, advisor Ion Stoica highlighted three primary pillars that make this technology transformative:
- Democratization (Cost): "You are going to have intelligence at your fingertips, and it’s going to be free because it’s going to run on the device you already bought," Stoica remarked. By removing the need for API tokens and subscription fees for cloud inference, PrismML is making high-tier AI accessible to anyone with a modern laptop.
- Privacy: By running the model locally, sensitive data never leaves the device. This is a critical requirement for healthcare professionals, lawyers, and government agencies who are currently hesitant to use cloud-based LLMs due to data sovereignty concerns.
- Latency: Local models eliminate the "round-trip" time to a server, allowing for instantaneous responses which are vital for real-time applications like voice assistants or augmented reality.
Hassibi emphasized that while 100% parity is the goal, the current 98% is already more than sufficient for the industry. He argues that benchmarks are often academic and that the surrounding software harness—the "wrapper" in which the model runs—often has a greater impact on the final user experience than a 2% variance in benchmark scores.
The Strategic Implications: The Future of Edge AI
The implications of PrismML’s breakthrough extend far beyond just saving disk space. We are witnessing the birth of "Edge AI," a paradigm shift where the "brain" of the AI is decentralized.
Impact on Hardware
As models like Bonsai 2 become the standard, hardware manufacturers may shift their focus. We could see a move away from massive VRAM requirements toward optimized "ternary processing units" designed specifically to handle +1, -1, and 0 operations with extreme energy efficiency. This could lead to a new generation of "AI-native" chips that prioritize logic gates over traditional floating-point math.
The End of the "Cloud Tax"
For startups and developers, the ability to ship a high-functioning LLM inside their own application—without paying monthly fees to OpenAI or Anthropic—changes the economics of the AI industry. It allows for "offline-first" AI applications, which can function in remote areas, on airplanes, or in secure facilities.
A New Era for Open Source
By using Alibaba’s Qwen as a base, PrismML is also strengthening the open-source ecosystem. It proves that open-source models can be refined and optimized to compete with—and perhaps eventually surpass—the proprietary "black box" models of Big Tech, provided the right compression techniques are applied.
Conclusion: Scaling Down to Move Forward
PrismML is proving that the path to Artificial General Intelligence (AGI) might not be paved with more GPUs and bigger data centers, but with smarter math and more efficient architecture. By successfully compressing Qwen3.8 27B into a mobile-friendly 5.9 GB package with 98% performance retention, they have crossed a Rubicon in AI development.
As the company looks toward compressing trillion-parameter models in the coming months, the goal remains clear: to make intelligence as ubiquitous and invisible as the electricity that powers our devices. If the rumors of partnerships with titans like Apple come to fruition, PrismML won’t just be a startup on the radar—it will be the engine driving the next generation of the digital world. For now, with over 13 million downloads and a rapidly maturing technology stack, the "small" models of PrismML are already making a very big impact.